Google DeepMind integrates TTS into Gemini, launches Flash and Lite voice models
Google DeepMind released two new text-to-speech models, Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS, now available on AI Studio and APIs. The Flash model ranks #1 on the Pronunciation Robustness Benchmark (89.5%) and #2 on the Provider Voice Arena Leaderboard. The models support voice design from natural language prompts, cloning from 30-second samples, and over 100 languages. This completes the voice interaction loop within the Gemini ecosystem, which has over 1 billion monthly active users, 63% of whom use voice.
 Illustration
Editorial responsibility
- No named human review is recorded for this page.
- Reports are grouped by semantic similarity and deterministic rules. Language models may assist titles, summaries, translation and cross-source analysis; the page reads the event directly, while its address stays stable when the title changes.
- Summary awaiting refresh
Summary awaiting refresh
Cross-source coverage
Reporting timeline
Google Integrates Text-to-Speech into Gemini, Launches Flash TTS and Lite Models
Google has integrated its text-to-speech (TTS) capabilities into the Gemini model family, releasing two new models: Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS. The Flash TTS model targets creative and high-expression scenarios, such as audiobooks and game characters, and scored 71.4 on Hume AI's Voice Design Benchmark. The Flash-Lite TTS is optimized for large-scale, low-cost applications like real-time voice agents. This move completes the voice interaction loop within the Gemini ecosystem, which already has over 1 billion monthly active users, 63% of whom interact via voice. The models support 130 and 101 languages respectively, and include features like voice cloning with consent and SynthID watermarking. Google's stock fell 3.6% on the day of the announcement. The strategic shift positions Google to compete on cost and ecosystem integration rather than standalone voice quality, targeting deployment in vehicles and IoT devices.
Read sourceGemini 3.8 Flash TTS tops AI pronunciation benchmark with 89.5% score
According to a post from Artificial Analysis, Google's Gemini 3.8 Flash TTS has achieved the top position on the Artificial Analysis Pronunciation Robustness benchmark with a score of 89.5%. It outperformed Gemini 3.1 Flash TTS at 88.2%, SpaceXAI TTS at 87.6%, and Gemini 3.8 Flash-Lite TTS at 87.4%. The benchmark evaluates various aspects of pronunciation. Gemini 3.8 Flash TTS led in Contextually Appropriate pronunciation at 97.9% and Expanding Shorthand at 86.1%. SpaceXAI TTS led in Preserving Exact Sequences at 85.7%, and Qwen-Audio-3.0-TTS-Plus led in Standalone Terms at 95.5%. The post invites readers to listen to examples from the benchmark.
Read sourceGoogle releases Gemini 3.8 Flash TTS, topping pronunciation benchmark and ranking #2 in voice arena
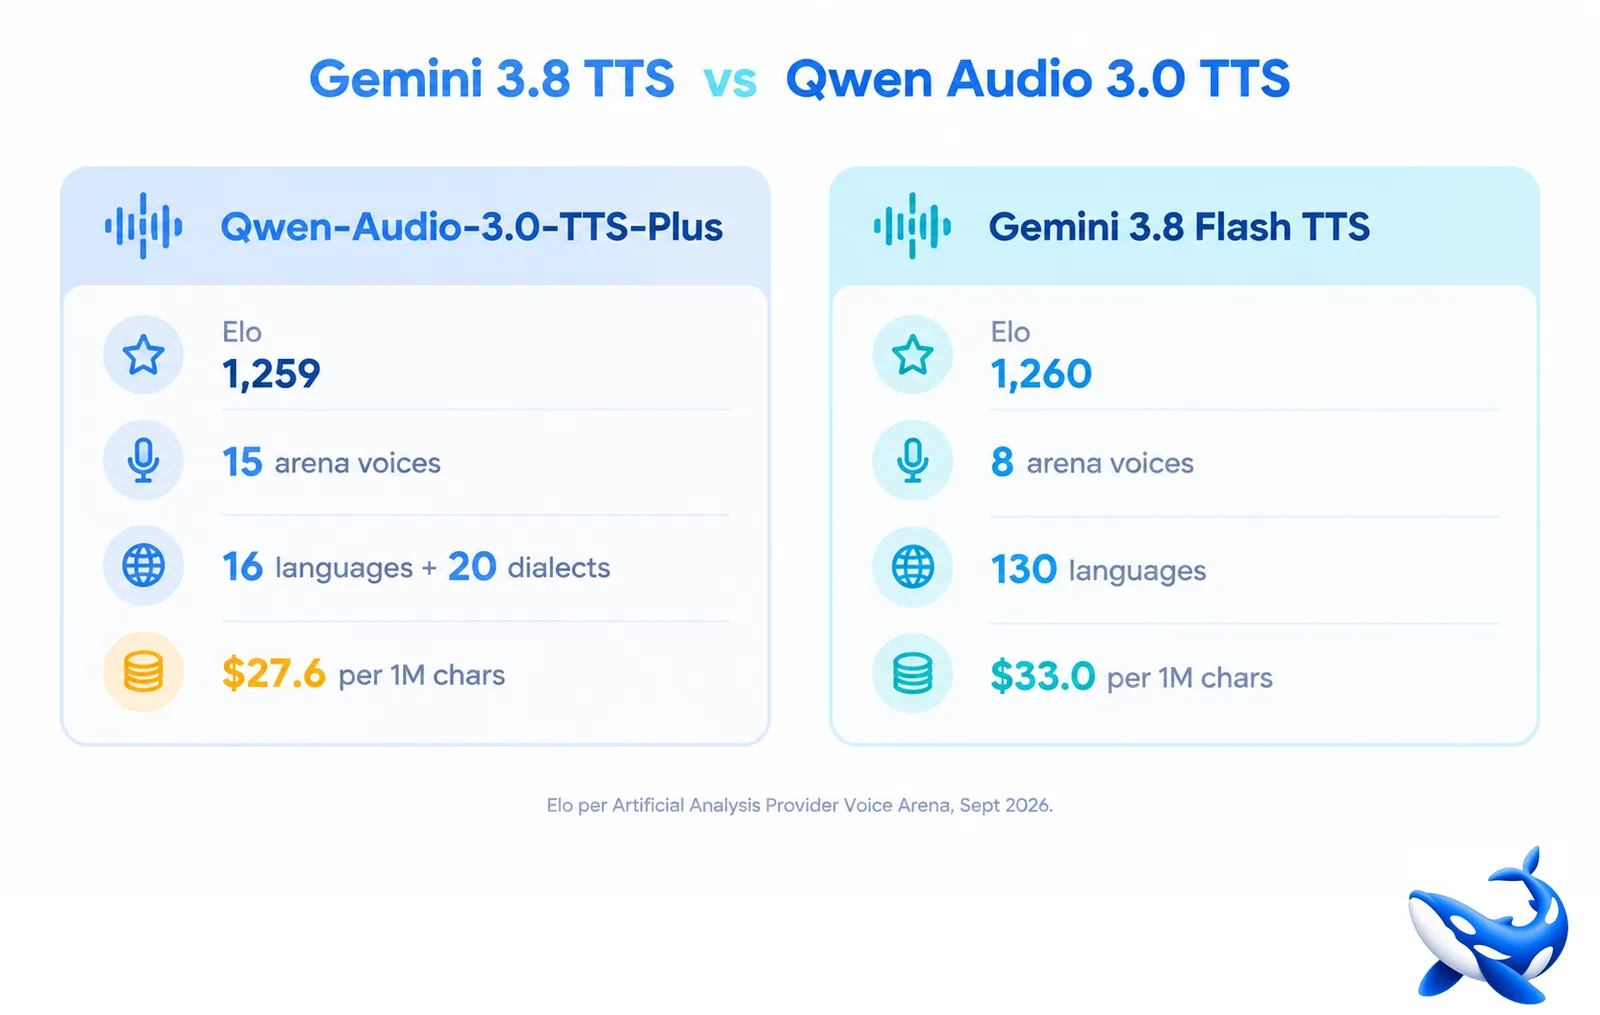
Google has released Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS, the latest text-to-speech models from Google DeepMind. According to the announcement, Gemini 3.8 Flash TTS debuts at #1 on the Pronunciation Robustness Benchmark with a score of 89.5%, ahead of Gemini 3.1 Flash TTS at 88.2% and SpaceXAI TTS at 87.6%. It also ranks #2 on the Provider Voice Arena Leaderboard with an Elo of 1,263, just behind Sonic 3.6 at 1,272 and ahead of Qwen-Audio-3.0-TTS-Plus at 1,260. Gemini 3.8 Flash-Lite TTS debuts at #6 with an Elo of 1,236. In multilingual controlled voice arenas, Gemini 3.8 Flash-Lite TTS ranks #1 in Japanese, #2 in Arabic, and #3 in German, while Gemini 3.8 Flash TTS ranks #2 in Japanese and Portuguese. The models process 44.1 and 40.2 characters per second respectively, approximately 2.7x and 2.4x faster than realtime. Pricing is set at $32.98 per 1 million characters for Flash TTS and $22.07 for Flash-Lite TTS, both more expensive than Gemini 3.1 Flash TTS at $18.31 but substantially cheaper than Eleven v3 at $100 per 1 million characters.
Read sourceShow 3 older updatesHide older updates
Google launches Gemini 3.8 Flash TTS and Flash-Lite TTS on AI Studio and APIs
Google has released two new text-to-speech models, Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS, now available on Google AI Studio and its APIs. The company describes the flagship model as designed for Voice Design and dual-speaker screenplay control, allowing users to prompt custom vocal personas, direct line-by-line delivery, and add vocal bursts. Google claims these are its most expressive audio generation models yet. The announcement was made via a post on X by the account testingcatalog, which is testing the new capabilities.
Read sourceGoogleDeepMind unveils Gemini 3.8 Flash TTS and Flash-Lite TTS for custom audio
GoogleDeepMind announced the release of two new text-to-speech models, Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS. The Gemini 3.8 Flash TTS model allows users to design unique voices with distinct accents and characteristics. The Gemini 3.8 Flash-Lite TTS model is built for efficiency and scale, enabling users to choose from their created styles or an expansive production-ready library. The announcement was made via an official post on X, highlighting the ability to create and deploy custom audio using these new models.
Google DeepMind Releases Gemini 3.8 Flash TTS and Flash-Lite TTS Voice Generation Models
Google DeepMind has announced the release of two new text-to-speech (TTS) models: Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS. The models support designing voices from scratch using natural language prompts, cloning a voice from a 30-second sample, and offer features such as line-by-line performance guidance, long-duration audio generation, and dual-speaker scene orchestration. The models cover over 100 languages. According to the official announcement, the company has detailed the models' capabilities, evaluation rankings, and access points for developers to assess their suitability for voice generation workflows.
Read source